Guide
How to prepare the data, where to find the answers the estimator asks for, and how to read the result. GA4 names are those of the English interface.
Create the exploration in GA4
The estimator reads a CSV exported from a free-form exploration. It takes a few minutes.
- In GA4, open Explore and choose Free form.
- In the Variables panel, at the top, set the date range. Four to twelve weeks is fine: a longer range doesn’t make the estimate more precise, but it adds rows.
- Next to Dimensions, click “+” and import Date and Session default channel group.
- Next to Metrics, click “+” and import Sessions, Total users, Key events, Transactions and Total revenue. The last four are optional: a site without ecommerce can skip transactions and revenue.
- In the Settings panel, drag Date and then the channel group into Rows. Leave Columns empty.
- Still in Settings, set Show rows to the maximum, 500, and leave Nested rows set to No.
- Further down, drag the metrics into Values. Leave Filters empty.
- At the top right, click the download icon (Export data) and choose CSV.
Column order doesn’t matter. The estimator recognizes columns by their name, not their position: the metrics can be in any order, in Variables as in Values.
The 500-row limit. The file has one row per day and channel, and GA4 exports at most the rows shown. For example, 49 days with about 10 channels a day make about 490 rows, just under the limit. With more channels or a longer period the extra rows aren’t exported and the estimator would see an incomplete period: shorten the date range. If it happens, the estimator tells you by comparing the rows with the total row.
A single key event. The “Key events” metric adds up all the property’s key events. Don’t filter the exploration by event name: the filter would also remove the sessions without that event, and the session estimate would be wrong. If the file contains several key events columns (for example “Key events: generate_lead” and “Key events: purchase”), the estimator asks which one to use.
What the file looks like. At the top there are a few comment lines starting with “#” (the property name, the exploration name, the date range). Then the headers, and right below them the total row: empty date and channel, the totals for the period, and the label “Grand total” in an extra column at the end. The other rows are one per day and channel; if a channel has no traffic on a day, the row is simply missing. Numbers use a decimal point and no thousands separator (for example 2177.6).
The total row. The estimator never adds it to the data. It uses it in two ways: to check that the file is complete, by comparing it with the sum of the rows, and to read the unique users in the period, which GA4 already counts without duplicates in the total row. It’s a figure from the file, like sessions and transactions: if the file is consistent with the total row, the estimator uses it on its own. Under “Improve the estimate” → “Users in the period” the card says where the value comes from (“Read from your export”, “Entered by you”, “Not available”), and you can change it or choose not to use it; the choice stays when you recalculate. The value isn’t in the link with the assumptions; the PDF and CSV state where it comes from.
Common file errors
When the file has a problem, the estimator shows the row and column. The most common cases:
- A column is missing. Usually Rows has a different dimension, for example “Session source / medium” instead of the channel group, or “Week” instead of “Date”. Fix the exploration and export again.
- The date isn’t valid. The Date column must hold days as YYYYMMDD (for example 20260315). This happens if you used “Week” or “Month”, or if the file was opened and saved in a spreadsheet that changed the date format.
- A number isn’t valid. A metric column contains text. It usually happens after a manual edit. Numbers can be written either way: 1,234.56 or 1.234,56.
- The file is empty or has only comments. The exploration had no data in the selected range, or another format was exported. Choose CSV, not Google Sheets, PDF or Excel.
- The Sessions column has only zeros. Check the exploration’s date range and filters.
- The rows don’t add up to the total row. The estimator flags it when the difference is above 2% (small differences are normal in GA4). Usually “Show rows” was below the maximum, the date range had more rows than the exploration shows, or the file was edited by hand. Fix it and export again.
The estimator handles on its own the comment lines GA4 puts at the top of the file, the total row (at the top or at the bottom), missing rows, empty cells and the “(not set)” channel, which it treats as a channel of its own. Besides the most common channels, GA4 may also list Organic Shopping, Paid Other, AI Assistant and Unassigned: they are channels like the others.
Find your consent rate
You’ll find the rate in the reports of the platform that runs your cookie banner (CMP). The estimator needs three things: the value, how it’s calculated (per visitor or per banner shown) and whether it includes visitors who ignore the banner without choosing.
Platforms name and calculate the rate differently. What follows sums up their official documentation; menu names change between versions.
- Usercentrics (Interaction Analytics). The “Accept Rate” is calculated only among visitors who interacted with the banner (accepts divided by accepts, denies and saves): visitors who ignore the banner aren’t included. The “Interaction Rate” is how many interacted compared with the times the banner was shown. For the estimator: rate = Accept Rate; “Does the rate include visitors who make no choice?” → No; as the share who ignore it you can use 100 minus the Interaction Rate.
- iubenda (the Privacy Controls and Cookie Solution Analytics tab; per-site figures need the Ultimate plan). Charts are calculated on pageviews, not visitors: the indicator comparing consents with the times the notice was shown matches “Per banner shown”. Pageviews where the banner was ignored are counted separately (“bounced”). Note that iubenda can count scrolling or closing the banner as consent, if you enabled those options.
- Cookiebot (Usercentrics). The dashboard shows the share of consents collected by the banner. Check the chart’s description to see whether visitors who ignore the banner are included; if it doesn’t say, answer “I don’t know”.
- OneTrust (the Cookie Consent Dashboard, with consent logging turned on). It logs interactions with the banner and the preference center (accept all, reject all, close, save). The available metrics depend on your setup: if you can’t find an explicit definition, answer “I don’t know” to both questions about the calculation.
In some tools this rate is called the opt-in rate.
If you have absolute numbers of acceptances and non-acceptances (declines plus visitors who ignore the banner), you can enter them in expert settings: the estimator derives a precise rate.
If the banner changed during the period, enter the date of the change and the new rate in expert settings.
Find out which Consent Mode is installed
- Basic: Google tags fire only after the visitor accepts. Visitors who decline leave no trace in GA4.
- Advanced: tags fire right away. Without consent they send cookieless pings, which Google can use to estimate the missing traffic.
To check: open the site in a private window, don’t accept cookies, and look with Tag Assistant (tagassistant.google.com) or in the Network tab of the developer tools for requests to Google Analytics. If there are any, it’s Advanced. Or ask whoever set up the banner.
Advanced alone isn’t enough for Google to actually estimate the missing traffic: it also needs the right reporting identity and a minimum traffic volume. The next two sections explain how to check.
Reporting identity
In GA4: Admin → Data display → Reporting identity. You need the Editor role on the property to change it, not to see it.
- Blended: uses User-ID, then the device ID and, where both are missing, modeling. It’s the only option that lets Google add an estimate of traffic without consent to the reports.
- Observed and Device-based: no modeling. Reports contain only observed data.
Changing the reporting identity doesn’t change the data collected and can be undone at any time, but the setting applies to every user of the property.
The data quality icon
It’s the small icon at the top, next to the title of the report or exploration. Hover over it to see one of these messages:
- “Including estimated user data”: modeling is active and the exploration already contains Google’s estimate. The estimator stops.
- “Excluding estimated user data”: the reporting identity doesn’t allow modeling.
- “Estimated user data unavailable”: the property doesn’t meet the thresholds (at least 1,000 events per day without consent for 7 days, and 1,000 users per day with consent on 7 of the previous 28 days), or the selected range is earlier than when modeling started.
Free-form explorations are among the few that include estimated data: that’s why this question matters for the very file you upload.
Compare with Google’s estimate
If modeling is active, the estimator adds nothing to the totals. You can still compare what Google added with what the estimator would have estimated.
- In Reporting identity, temporarily switch to Device-based.
- Reopen the same exploration, with the same date range, and export it again: it will contain only observed data.
- Switch the reporting identity back to Blended right away.
- In the estimator, at the Consent Mode step, upload this second file and fill in the consent rate.
The comparison table shows, for each metric, how much Google added and the estimator’s range. A result “outside the range” doesn’t tell you who is right: the two methods use different information.
Read the results
- The main figure tells you what share of sessions GA4 shows you. “Likely between X and Y (8 times out of 10)” is the range that, on test data, contains the true value about 8 times out of 10, if the assumptions are right.
- The cards give the estimated totals for sessions, transactions, revenue and key events, with the observed value, the missing part and the wider range (“almost certainly”, 19 times out of 20).
- By channel is the least solid part: it assumes consent is similar across channels. Read it as a pointer, not a measurement.
- How solid this estimate is shows which assumption weighs most and how the total would change if it were wrong. It’s the place to find out which data is worth getting.
- Assumptions marked Default weren’t chosen by you: check and confirm them, or change them.
Use real orders
Orders from your order system are the data that most improves the estimate of orders and revenue. Enter them only if they are comparable with GA4:
- website orders only, for the same period as the file;
- without phone, in-store or marketplace orders, automatic subscription renewals, test or canceled orders;
- revenue with the same definition as GA4: the same choice on tax, shipping, discounts and refunds.
If you see “Fewer orders are missing than your answers predict” (or “More orders are missing…”), the orders GA4 didn’t record don’t match the ones your answers predict, between those lost to consent and those lost to other causes. It isn’t an error: it tells you that probably one answer, or one of the figures you entered, doesn’t describe the site well. The estimator shows the comparison in a figure and, for each answer about the audience, whether the numbers would add up with it; it then lists the points to check that can’t be calculated: the order period, the scope, the consent rate and, if fewer orders are missing, transactions counted twice in GA4. Until the numbers add up, orders and revenue are estimated without real orders; sessions and users don’t change. See also More or fewer orders are missing than predicted.
What audience does the site have?
With real orders, the estimator asks what audience the site has. The answer splits the missing orders between those missing because of consent and those GA4 misses for other reasons, mostly ad blockers and browsers that block Google Analytics. It matters: choosing the wrong one shifts the estimated transactions by about 15%.
| Answer | Value used | Typical sites |
|---|---|---|
| Consumer, mostly mobile | about 7% | fashion and accessories, beauty, groceries, home and furniture, recipes and lifestyle, family travel bookings; more than half of traffic from smartphones |
| Technical or professional, mostly desktop | about 20% | software and SaaS, hosting and domains, electronic and computer parts, industrial supplies, developer or marketing tools, technical publishing |
| Mixed / I don’t know | about 9%, wide range | general catalogs (for example consumer electronics), publishing, sites with several audiences; or when you don’t know your audience well enough |
| I use server-side tagging or my own proxy | about 2% | GA4 goes through your own domain (for example a Google Tag Manager server on a subdomain): ad blockers catch it much less often |
Two clues you can find in GA4: the share of sessions from desktop (above 60% suggests a professional audience) and the share of visits from Firefox and Brave, the browsers that block most. If in doubt, choose “Mixed / I don’t know”: the range gets wider, but stays honest. If you know the value, you can enter it in expert settings.
Getting the most from the Estimator

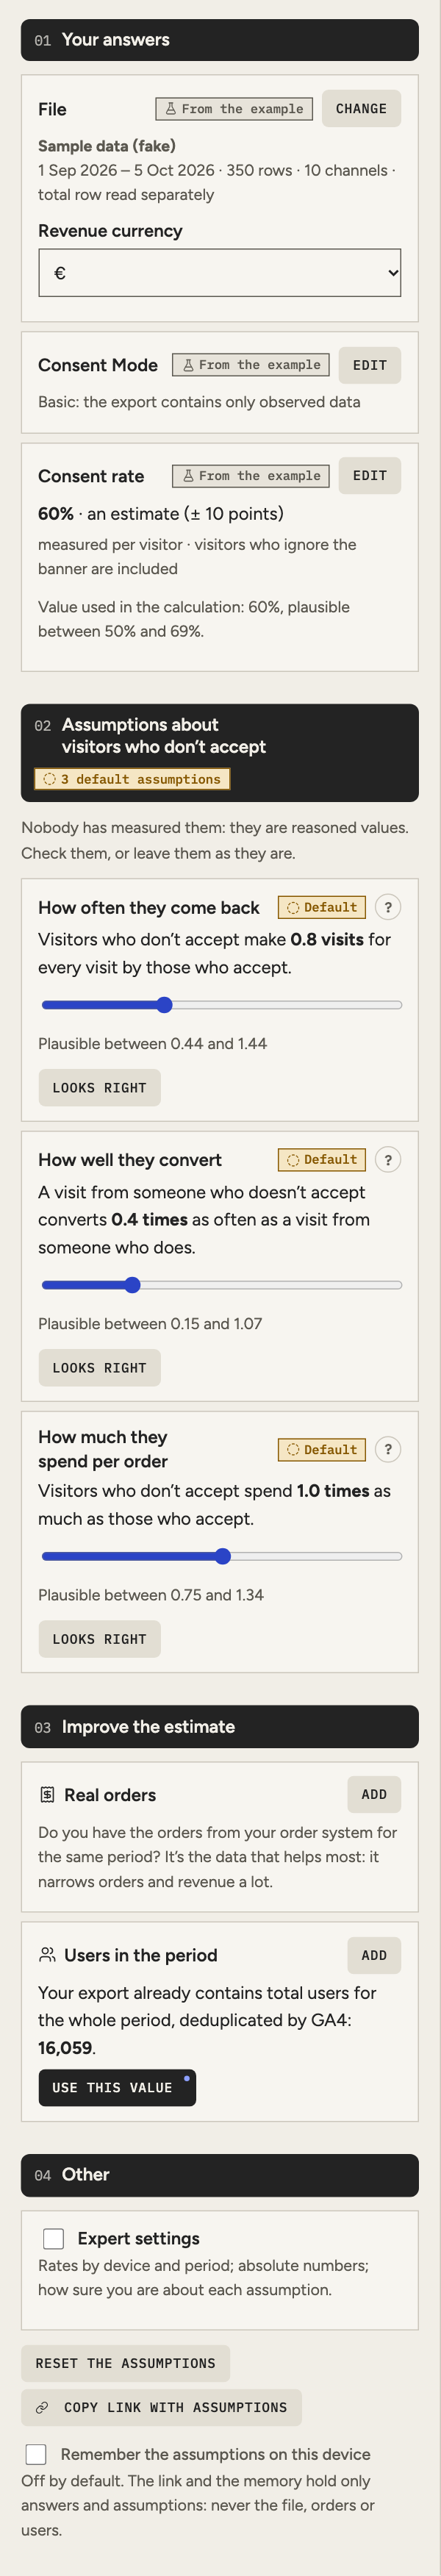
The left column holds everything that decides the result, in four sections:
- 01 Your answers. The file, Consent Mode and the consent rate: this is your data, and without it the estimate doesn’t start.
- 02 Assumptions about visitors who don’t accept. How often they come back, how well they convert, how much they spend per order: nobody measures them, so they start from reasoned values marked “Default”.
- 03 Improve the estimate. Real orders from your order system and users in the period: extra data that narrows some of the figures.
- 04 Other. Expert settings (rates by device and period; absolute numbers; how sure you are about the assumptions), the link with assumptions and memory on this device.
The “?” button next to a question or an assumption opens a short explanation, with a link to the part of the Guide or the Method that covers it.
I want a narrower range
- What to do
- Look first at “How solid this estimate is”: it tells you which source the uncertainty comes from. If the consent rate weighs most, make it more reliable: check in your CMP how it’s calculated and, if you have the absolute numbers of acceptances and non-acceptances, enter them in expert settings. If “how well they convert” weighs most, enter the real orders from your order system.
- What changes
- A rate declared “I know it precisely” or absolute numbers narrow the session range. Real orders narrow orders and revenue a lot, but not sessions: they tell you how many orders are missing, not how many visits. Uploading more days doesn’t help: the range depends on the assumptions, not on noise in the data. Don’t tighten the assumptions just to get a sharper number: if the range doesn’t match what you know, it promises more than it delivers. Why
I changed the banner during the period
- What to do
- Open expert settings → “Rate changes during the period” and enter the date of the change and the new rate. The main rate applies from the start of the file until that date.
- What changes
- In the Validation tests the totals stay correct whether or not the change is declared; what changes is how they split across days, so it matters mostly for the “Day by day” chart. The assumptions about visitors who don’t accept stay the same for the whole period: a different banner changes how many accept and, in principle, who accepts, and this is a stated limit.
Consent differs between mobile and desktop
- What to do
- In expert settings → “Rates by device”, enter for each device its consent rate and the share of sessions you see in GA4. At least two rows are needed.
- What changes
- The estimator derives the overall rate from them, which replaces the percentage in your answers. Results aren’t split by device, because the export doesn’t contain the device. In the Validation tests, with differences like those tested (50% consent on mobile and 75% on desktop, one and a half times the visits on desktop), the overall rate alone overestimates sessions by about 4%; with rates by device the error disappears. With bigger differences the error grows; if visits are similar across devices, the overall rate is enough. Learn more
One channel accepts much less than the others
- What to do
- Nothing to enter. The total isn’t affected by differences between channels; read that channel’s figure as indicative.
- What changes
- In tests with very different consent across channels (30% to 85%) the total stays correct (coverage 79 out of 100), while the session range for a single channel contains the true value less than half the time. If consent varies little across channels (within about 15 points of the overall rate, as the estimator assumes), the channel breakdown holds too: coverage about 80 out of 100. Learn more
I don’t know how to answer the assumptions
- What to do
- Leave them as they are if you have no data: the default values are reasoned and already have a wide plausible range, which goes into the range of the result. Move them only if you know something about your audience, for example from a cookieless analytics tool. Click “Looks right” once you’ve read them and they seem reasonable for your site.
- What changes
- “Looks right” doesn’t change the numbers: the assumption goes from “Default” to “Confirmed”, in the PDF too, and the count of default assumptions in the CSV goes down. Moving a slider does change the results, and “How solid this estimate is” shows how much each assumption weighs. For “how well they convert” the best remedy is real orders, which replace it. The assumptions in the Method
More or fewer orders are missing than predicted
- What to do
- Read the comparison: the orders actually missing (order system minus GA4) and those your answers predict, split between consent and other causes (ad blockers, payments through an external service the customer doesn’t return from, errors in the purchase tag). If an answer about the audience is marked “compatible with your data”, choose it only if it really matches the site: it isn’t a way to make the numbers add up. Then check the order period, the scope (phone, in-store, renewals, other sites), the consent rate and, if fewer orders are missing, transactions counted twice in GA4.
- What changes
- Until the numbers add up, orders and revenue are estimated without real orders, from the assumptions alone; sessions and users don’t change. Once they add up, real orders replace the “how well they convert” assumption and narrow the range for orders and revenue. The technical value that would be needed is under “Details” in the box. Learn more
I need to present the estimate to a client
- What to do
- Before exporting, confirm or change the default assumptions. Then, under “Take the results with you”, choose Print or save as PDF: the PDF has a header with the date and lists your answers and the assumptions used, each with its state (Default, Confirmed, Changed). Download CSV gives you the same numbers in a table. With Copy link with assumptions a colleague can reopen the Estimator with the same answers and assumptions: the link doesn’t contain the file, orders or users, so they’ll need to upload the export to see the numbers.
- What to say
- Present the result as a range, not a single number: “likely between… (8 times out of 10), if the assumptions are right”. Show the channel breakdown as a pointer, and the limits are those of the estimate: see Limits.
Frequently asked questions
What period should I use? Four to twelve weeks. A longer period doesn’t narrow the range: the uncertainty comes from the assumptions, not from the number of days.
Does it work for a site without ecommerce? Yes. Without transactions and revenue, the estimator estimates sessions, users and key events.
Can I use it for several properties? Yes, one at a time: each file is read separately and nothing is kept.
Why do conversions grow less than sessions? Because visitors who don’t accept cookies convert less, on average, than those who do. That’s the “How well they convert” assumption, which you can change.
How is this different from Google’s modeling? Google estimates traffic without consent from the cookieless pings of Consent Mode Advanced, if the property meets the thresholds. The estimator estimates it from your consent rate and stated assumptions. Don’t use both on the same data.
My site is in the United States, or in a country without prior consent. Does it apply? The estimator assumes opt-in consent: tracking starts only after the visitor explicitly accepts, as EU and UK rules require for analytics cookies. Under an opt-out model, common in the United States, tracking runs until the visitor objects, and visitors who ignore the banner are tracked. The missing share is then usually much smaller, and what matters is the share of visitors who opt out, not those who accept. You can enter the share of visitors still tracked as the consent rate, with “Yes” to the question about visitors who ignore the banner, but the default assumptions were designed and tested for opt-in: treat the result with extra caution. If your site serves both regions with different banners, only the opt-in part fits the estimator.
Can I share the assumptions with a colleague? Yes, with “Copy link with assumptions”. The link holds only answers and assumptions: never the file, orders or users.
Does the estimator keep anything? No, unless you turn on “Remember the assumptions”. See the Privacy page.